AI-Assisted Equipment Specification Extraction From Technical Documents
Machine learning extracts equipment specs from PDFs, eliminating manual data entry errors.
Here's what happens on almost every data center project. A manufacturer sends over a PDF submittal for a UPS or a PDU. An engineer opens it, finds the voltage rating, and types it into the BIM model. Then types it again into the equipment schedule. Then again into the cable routing tool. Then again in the RFI response when someone asks a clarifying question. Same number, four separate keystrokes, four separate chances to fat-finger a digit.
That's the workflow, and everybody in the industry has lived it in some form. It's not glamorous, so nobody writes about it. But it's where a huge amount of design time disappears, and worse, it's where errors get born.
Each manual re-entry is a traceability break. The value sitting in the schedule might not match the value in the model anymore, and there's no alarm bell, no flag, nothing that tells the team the two have drifted apart. They just sit there, quietly disagreeing with each other, until someone notices during a walkthrough or, worse, doesn't notice until commissioning.
Rack moves show this problem in its full ugly form. Moving one rack changes the power draw, changes the cooling load, changes cable routing, and requires every schedule and sheet referencing that rack to be updated. If the specs backing all of that live in scattered PDFs, that whole cascade has to happen by hand, one field at a time, across however many documents touch that rack.
None of this is a knock on the engineers doing the work. They're doing what the process asks of them, competently and carefully. The workflow itself is the failure, not the people stuck inside it.
What AI-assisted extraction does to a technical document
Manufacturer datasheets are semi-structured documents: tables that break across pages, footnotes that qualify a number three sections away, multi-column layouts, and units that switch between metric and imperial without warning. They're semi-structured documents: tables that break across pages, footnotes that qualify a number three sections away, multi-column layouts, and units that switch between metric and imperial without warning. A human reader parses all of that instinctively. A simple keyword search chokes on it.
Document AI, sometimes called document intelligence, is the field built to handle exactly this mess. It applies machine learning, including natural language processing and transformer architectures, to pull structured information out of documents where spatial layout and text meaning are tangled together. The common use cases are blunt and practical: cut down on manual data-entry mistakes, and surface data that used to be locked away inside PDF silos nobody wanted to open.
Two extraction strategies matter here, and they solve different problems.
Schema-based extraction gives the system a target list, things like "input voltage," "heat dissipation," "rack unit height," and the system hunts through the document for values that match. This works well when the equipment category is known ahead of time and the fields it needs are predictable, which describes most data center gear.
RAG-augmented extraction (retrieval-augmented generation) takes a different approach. Extracted content gets stored in a vector database, then pulled back up at query time to ground an AI answer in the original document text instead of letting the model guess. One study measured this directly: Recall went from 0.636 to 0.926, and Accuracy climbed from 0.595 to 0.807, across 960 golden question-answer pairs, compared against a commercial PDF chat tool used as the baseline.
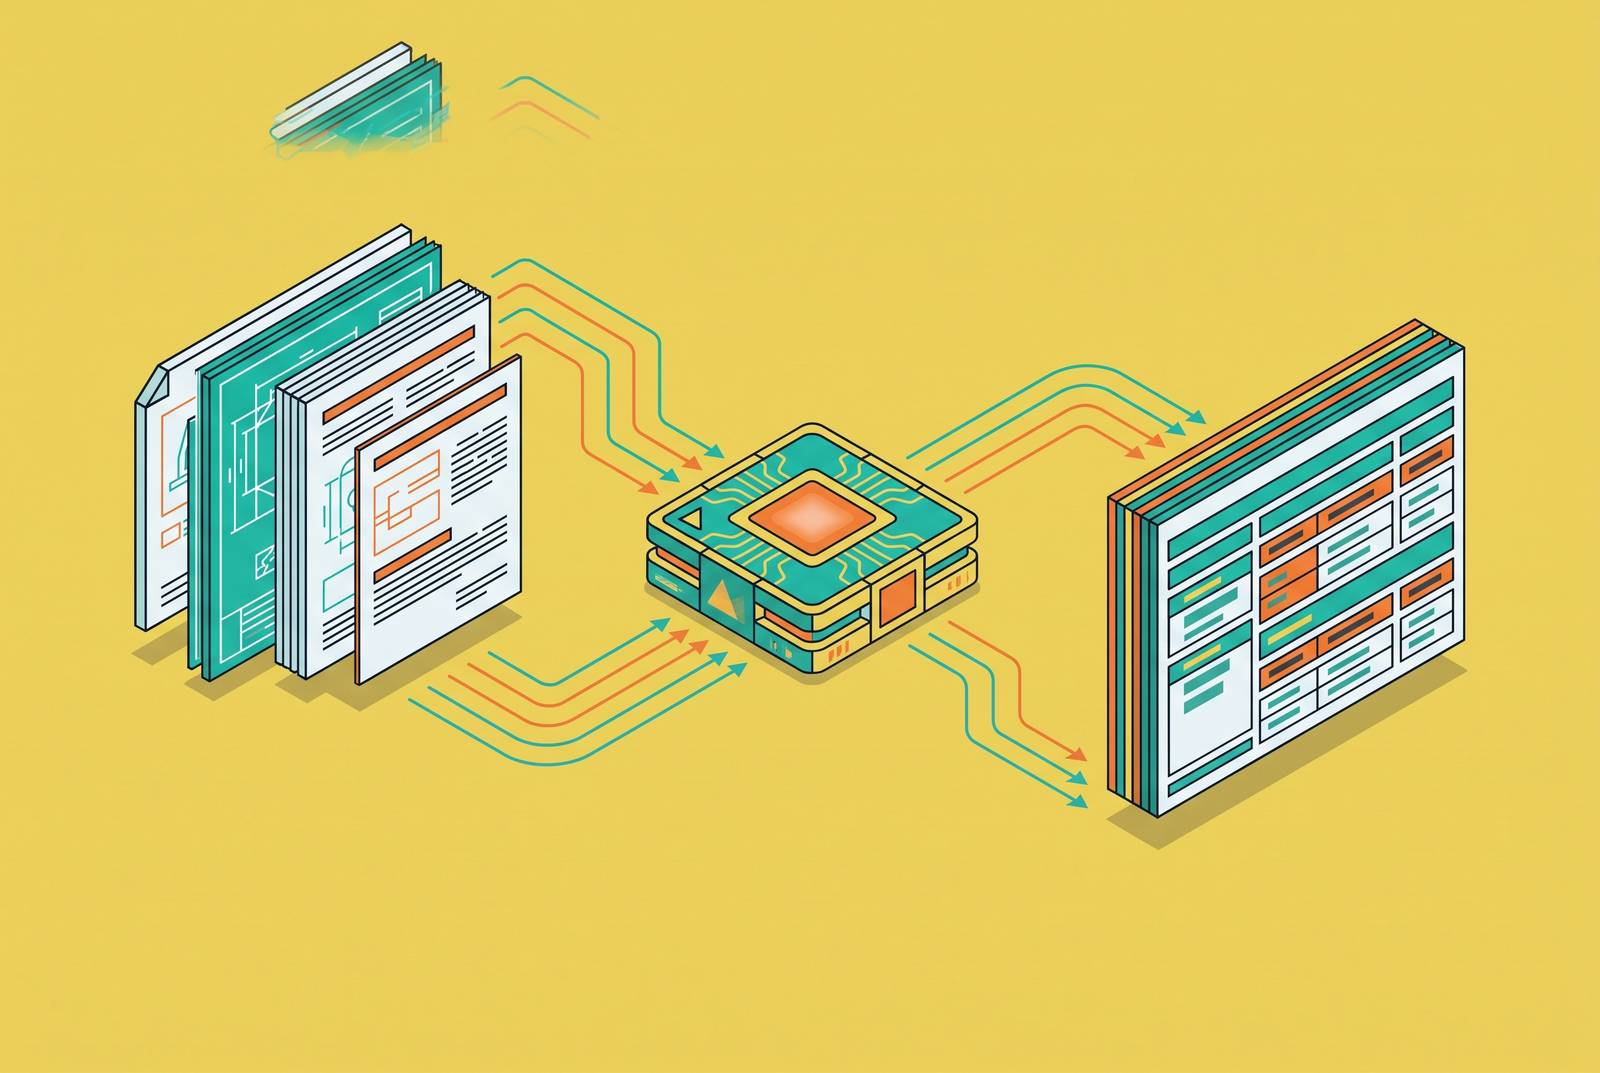
The output that matters here is structured data. It's structured data, values mapped to fields, ready for a BIM family, an equipment schedule, a validation rule, or a DCIM asset record to consume directly. No human has to sit in the middle retyping anything.
Where extraction accuracy is today
A Sensors (Basel) study tested schema-based extraction combined with RAG on IoT device datasheets and hit an Accuracy of 0.807. That's a real jump over baseline methods, and it's good enough to matter in production. But it's a ceiling, not a guarantee.
Compare that to a separate 2026 peer-reviewed study on LLM-based information extraction from BIM files, which found the best configuration tested topped out at 55 to 57 percent accuracy. That number leaves a wide margin of error for any workflow where precision matters. That's not a small gap between the two results, and it's not random either.
The difference comes down to what's being asked. Reading a clearly labeled field off a datasheet, "Input Voltage: 208V," is a much narrower task than interpreting geometry and relationships buried inside a BIM file, where the same information might be implied by object placement rather than stated in text.
Extraction accuracy is high enough right now to cut out most manual keying for well-structured datasheet fields, things like voltage, current, weight, and dimensions. It is not yet accurate enough to replace a human signing off on any value that feeds into a safety or code-compliance calculation. Those are two different jobs, and the technology is ready for one of them.
Why power and cooling specs cannot tolerate extraction gaps
Rack densities for AI workloads aren't just going up, they've moved into a different category. An industry group's whitepaper on data centers for AI notes rack power densities have already increased by more than an order of magnitude compared to traditional general-purpose racks, and the roadmap points toward another order of magnitude on top of that, aiming at 1 MW per rack.
Even that headline number doesn't settle the question of what a given deployment actually draws. Actual consumed power for an AI data center supporting a fixed number of GPUs varies a lot across the industry, shaped by operating points, workload mix, software efficiency, cooling method, and how power delivery is architected. The spec sheet value is a starting point for design, not a final answer.
That variability is why extraction needs to feed into validation rather than standing in for it. If a UPS or PDU spec gets misread, and the wrong load figure lands in the model, that single error works its way through power distribution sizing, cooling capacity planning, and structural loading calculations before anyone catches it. By the time it reaches construction, it has grown from a typo into a change order.
Analysis of rising AI rack densities makes a related point: operators now have to coordinate power, cooling, facility design, and grid constraints far more tightly than before. More specs in play, more systems depending on each other, means more places where a single manual re-entry error can cascade into something expensive.
The path from extracted spec to operational asset record
Three systems need structured asset data the moment a building hands over from construction to operations. The BMS handles facility-level HVAC and environmental control. The EPMS covers electrical distribution and energy metering. DCIM ties IT and facility systems together with real-time analytics and open APIs that talk to BMS, EPMS, and ITSM platforms.
Right now, almost none of that data arrives automatically. It gets assembled by hand from construction documents at turnover, and spec values that were manually entered during design often have to be re-entered again for the DCIM record at turnover. That's not a hypothetical inefficiency, it's a recurring pattern across the industry.
A proper structured handoff needs equipment identity, location, electrical characteristics, cooling load, and maintenance intervals, and every one of those values should trace back to the original manufacturer document it came from.
If extraction happens once, at design time, and that structured record carries forward instead of getting rebuilt from scratch, DCIM, EPMS, and BMS can all pull from the same source data directly. That eliminates a second round of manual re-entry, and it closes off the traceability break that comes with it.
Extraction use in a connected workflow versus a standalone tool
A standalone extraction tool reads a PDF and spits out a spreadsheet. That's useful, no argument there, but the spreadsheet is just a new silo. Someone still has to manually pull those values into the model, into the schedule, into whatever system tracks RFIs. The bottleneck moves, it doesn't disappear.
Connected extraction works differently. The spec data flows directly into smart equipment components, validation rules, cable routing constraints, and asset registers, all from a single extraction event. Write once, read many times, across every system that needs the value.
Here's a fair test for telling the two apart: when a manufacturer issues a spec revision, or the team approves a substitution, count how many places update automatically versus how many need someone to go in and fix it by hand. That count tells you whether extraction is actually wired into the workflow or just sitting upstream of another manual step wearing a nicer interface.
ArchiLabs Studio is built around the connected version of this. It places smart equipment using data pulled straight from specs, routes power, cooling, cable tray, and fiber using automation recipes, and carries that structured data through to DCIM, EPMS, BMS, and whatever handoff system the owner uses. Extraction isn't a one-time import here, it's a data relationship that stays live across the project.
Where deterministic rules must take over from AI extraction
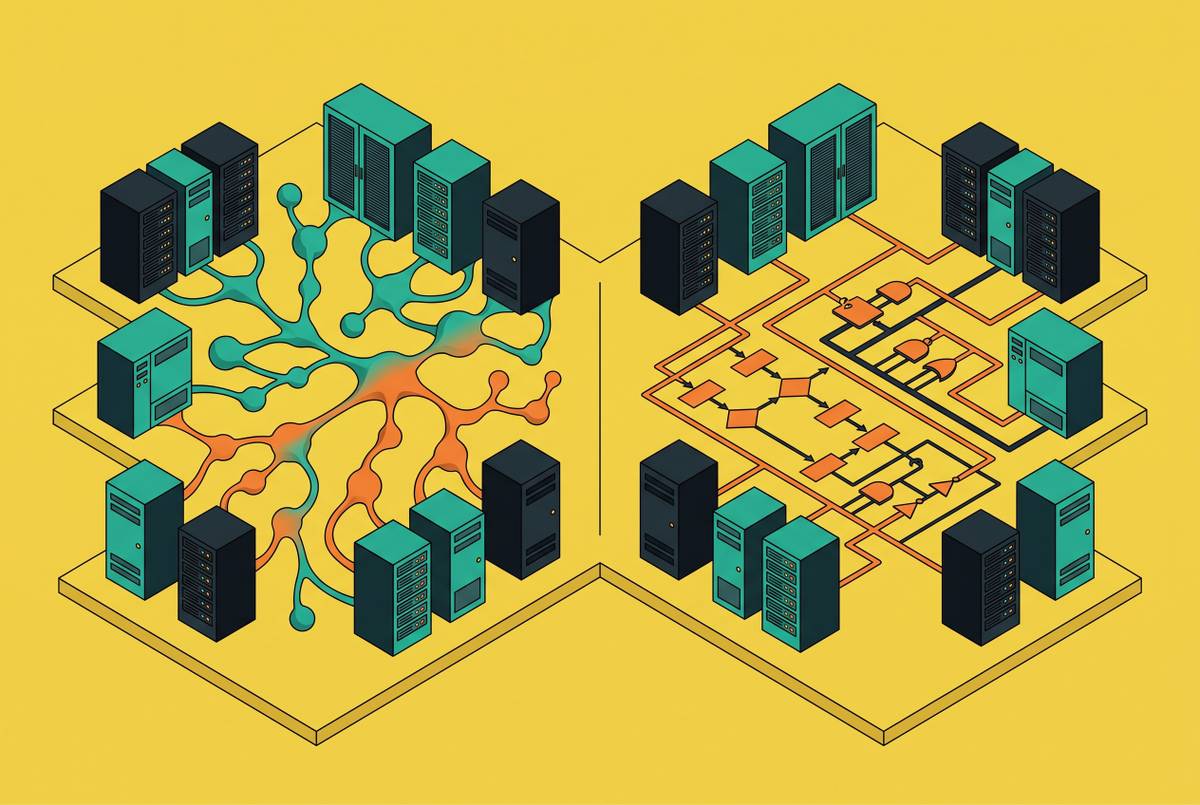
AI is the right tool where flexibility and language comprehension matter: reading documents that vary in layout, parsing a footnote written in plain language, handling the messiness that comes with real manufacturer paperwork. Deterministic rules are the right tool where precision and safety aren't negotiable. Mixing up which one belongs where is how mistakes get built into a design.
A handful of examples make the line clear:
- Power circuit capacity validation: extracted draw values get checked against breaker ratings. That's arithmetic, not inference.
- Code compliance: equipment clearances, egress paths, arc flash boundaries. These have to be enforced by rules with no room for "close enough."
- Cooling load budgeting: extracted heat dissipation numbers get summed and checked against room cooling capacity. A deterministic calculation, and it has to match, not approximately match.
- Cable sizing: current ratings pulled from specs get checked against conduit fill and derating tables. That's a table lookup, not something a language model should be guessing at.
Teams that treat AI extraction as a black box, trusting whatever comes out without running it through deterministic checks, are the ones who find their errors during construction instead of during design review. By then the fix costs a lot more than a second look at a schedule would have.
The 55 to 57 percent accuracy ceiling from that 2026 BIM extraction study backs this up with hard numbers. Even the best-performing configuration tested got it wrong roughly 43 to 45 percent of the time. No engineering team can live with that failure rate on a safety check or a compliance check without a validation layer standing between the AI's output and the final decision.
Evaluation criteria for extraction in a data center delivery workflow
Schema coverage. Does the tool already understand data center equipment categories, UPS units, PDUs, CRAC and CRAH systems, liquid cooling CDUs, network switches, cable management, or is it generic document AI that has to be taught every one of those schemas from zero?
A validation layer. Does the tool run extracted values through deterministic rules before anyone acts on them, or does it hand over raw output and stop there? For anything touching power, cooling, or code compliance, this isn't optional.
Downstream connectivity. Once a value gets extracted, where does it go? Into a proprietary format nobody else can read, into an exportable spreadsheet that still needs manual import, or directly into BIM families, schedules, and asset registers that feed the operational systems that actually run the building?
Traceability. Can any value sitting in the model or the schedule be traced back to its source document and the specific extraction event that pulled it? Or does that provenance vanish the moment the import finishes, leaving nothing but a number and no way to check where it came from?
Those four questions cut through a lot of vendor talk fast. A tool that answers all four well isn't just faster than manual re-entry, it's building a record that holds up under a walkthrough, an audit, or a rack move three years down the line.