BMS Integration Data Requirements at Data Center Turnover
Four specific data sets must arrive complete at BMS handover or systems fail on day one.
A data center can pass every commissioning test and still fail on day one, because commissioning verifies that equipment works, not that the data behind it is complete. BMS integration at turnover depends on four specific data sets, point lists, equipment parameters, alarm configurations, and control logic, arriving in a form the system can actually use. This piece walks through what each of those looks like, where it comes from in the design and construction process, and what breaks when it is delivered half-finished.
The three-layer control architecture and what each layer needs to receive
A data center runs three control systems at once, and they don't operate independently.
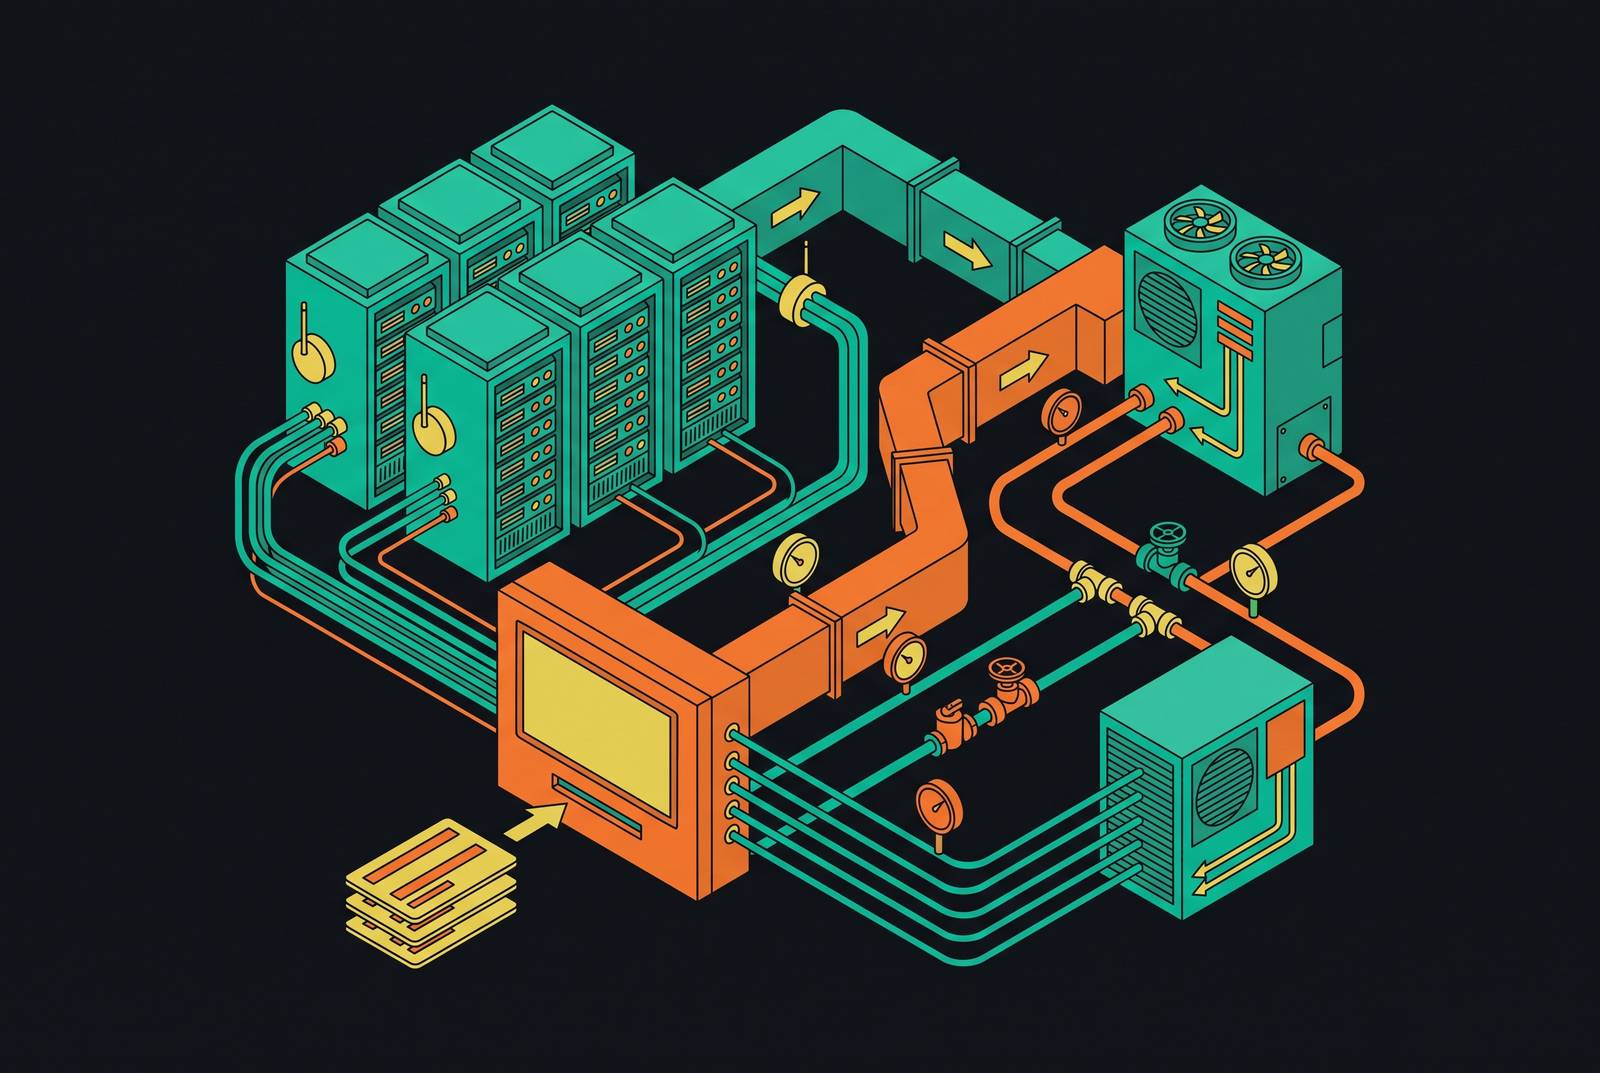
The BMS handles cooling: chillers, CRAC and CRAH units, pumps, air handlers. It runs mostly on BACnet and DDC protocols and needs setpoints, sequences of operation, sensor assignments, and mechanical equipment parameters to function. The SCADA layer sits above it as the operator's single view into the building, pulling data from the BMS, the power systems, and field PLCs. It needs unified alarm configurations, trend definitions, and mappings that let data from different domains show up on one screen without translation errors. Then there's EPMS, the electrical monitoring layer, watching utility feeds, switchgear, UPS units, generators, and PDUs. It tracks voltage, current, power factor, and consumption, and it needs meter configurations and load data at every point in the power chain.
Here's why the three-layer split matters operationally, not just architecturally: EPMS catches electrical events at the millisecond level, far faster than BMS can react on its own. That speed difference has to be built into how alarms get routed at handover, or the layer that spots trouble first isn't the layer that tells anyone about it.
A standard BMS physical hierarchy sits beneath all three layers: field level (sensors and actuators), automation level (controllers), and management level (the operator interface, where DCIM integration usually happens). The automation level has to respond in the 100 to 300 millisecond range, and that speed requirement shapes which hardware and protocols are even acceptable, plus what the point list has to say about scan rates. None of this holds together if any layer runs on a closed or proprietary integration. Open protocols mean someone besides the original vendor can read the data. Proprietary ones mean that when the vendor leaves, so does the only person who understands the system.
A power event becomes a thermal event within minutes. A gap in EPMS data doesn't stay an EPMS problem; it becomes a BMS problem before anyone's finished writing the incident report.
What a complete point list contains
The point list is the master index of everything the BMS watches and controls: field device, controller address, point name, engineering units, scan rate, alarm limits, trend configuration. A large data center runs roughly 70,000 of these points, as proconexdirect.com's integration checklist notes, and every single one needs point-to-point verification, meaning someone physically confirms the signal travels from field device to controller correctly labeled and correctly scaled.
Naming affects whether alarm correlation and trend analysis work correctly once the facility opens. A point called "AHU-1-SA-T" in one system and something else in another breaks alarm correlation and trend analysis before the facility even opens. For each point, the list needs to carry:
- Physical location and controller or panel address
- Point type (analog input, digital output, and so on)
- Engineering units and scaling
- Normal operating range plus alarm thresholds, high warning, high alarm, low warning, low alarm
- Trend interval and how long data gets retained
- Alarm priority and where it routes
- Which team or role owns the response
Unvalidated points don't announce themselves as a problem. Industry controls staffing research finds that incomplete points and weak alarm routing often stay hidden until commissioning, or worse, until live operations, right around the time the controls vendor has already packed up and left.
There's also a format problem. A point list that lives only inside the BMS vendor's own configuration tool can't be checked by the operations team, and it can't feed DCIM or EPMS platforms either. Irecruit's guide states that the BMS spec needs to lay out network architecture, hardware, software, and integration protocols, and the point list itself should carry protocol assignments, BACnet object type, Modbus register, whatever applies, so downstream systems can pull the data in without someone re-typing it by hand.
Equipment parameters: what must be extracted from manufacturer documentation before turnover
Every piece of control logic depends on numbers that live in equipment specs, including a chiller's minimum and maximum load, a pump's performance curve, a UPS transfer time, a generator's ramp rate, and the acceptable range for a cooling unit's supply setpoint. These numbers start out in manufacturer submittals and data sheets, and those documents usually arrive as PDFs during the submittal review, not as anything a machine can read.
That's the gap: parameters trapped in a PDF can't be checked against what actually got programmed into the BMS. Parameters trapped in a PDF can't be checked against what actually got programmed into the BMS, and mismatches between the submittal and the real configuration are a common defect that hides until functional testing forces it out into the open. For each major piece of equipment, the BMS needs:
- Operating ranges (temperature, pressure, voltage, current) it's allowed to command within
- Manufacturer-specified alarm setpoints, not defaults left over from a previous job
- Startup delays, minimum run times, and lead-lag logic for redundant units
- Rated capacity figures for calculating load fractions and triggering load shedding
- The communication interface spec, BACnet object list, Modbus register map, or vendor gateway config
Skipping this extraction step leaves the operations team with a BMS running on guesses, sometimes setpoints made conservative just to avoid tripping faults during testing, never tuned for how the facility actually runs under load. Sound data center BMS practice holds that commissioning should include calibration verification, confirming the programmed parameters match how the installed equipment actually behaves, not just how the spec sheet says it should behave.
The underlying point holds here too: equipment data sitting in a PDF is intelligence nobody's using. It needs to flow into models, schedules, and validation rules directly, and the same logic applies to BMS parameters. They need to reach the controls configuration in a structured form someone can trace back to its source, not retyped from a document three people ago.
Alarm configurations: routing, priority, and escalation logic as handover deliverables
An alarm that's mislabeled, misrouted, or set to the wrong priority does the same thing as no alarm at all, except worse, because it looks like the system is working. Proconexdirect.com identifies alarm escalation logic as one of four recurring, preventable causes of BMS integration failure, and it's also one of the things most often left unfinished the moment the controls vendor walks off site.
A complete alarm package specifies:
- Priority: critical (respond now), major, minor, or informational (log it, don't wake anyone up)
- Routing: which team gets which alarm, through which channel, BMS console, SCADA screen, EPMS alert, email, text, DCIM notification
- Escalation: if nobody acknowledges within a set window, who gets notified next and how
- Suppression rules: which alarms go quiet during planned maintenance, and who's allowed to flip that switch
- Cross-system correlation: a generator transfer alarm that should also nudge the cooling sequence into action, for instance
Industry handoff guidance is consistent that someone has to actually check point names, alarm priorities, routing, trends, access rights, and escalation logic before turnover counts as done. That's not something a signature on a punch list can substitute for. It takes a controls owner on the operations side who can read the configuration and push back on it if something's wrong.
Point-to-point testing and alarm validation aren't the same test, either, even though they're easy to conflate. A point can pass its physical checkout, the signal appears correctly and the value reads correctly, while its alarm threshold or its routing is still wrong. Run them separately. Document them separately. Uptime Institute's 2025 Annual Outage Analysis, cited via broadstaffglobal.com, found that human-error outages climbed by a 10-percentage-point margin tied to procedures not being followed, and alarms nobody trained operators on are a direct piece of that pattern.
Control logic and sequences of operation: what must be documented before the vendor leaves
Control logic is the programmed rulebook: when a standby chiller kicks on, how cooling ramps back up after a generator transfer, how non-critical loads get shed when power's constrained. Sequences of operation are the written spec that logic gets built from, and in theory they match the as-built programming. In practice, they often don't, because field changes made during construction rarely make their way back into the design document.
At handover, the operations team needs:
- As-built sequences reflecting what's actually programmed, not the design-intent version from the construction docs
- Annotated control diagrams laying out the decision logic for normal operation, failover, recovery, and manual override
- PLC and controller program backups in a format the team can read, restore, and edit without calling the original vendor
- A change log tracking every deviation from spec made during construction and commissioning, why it happened, and who approved it
In practice, most integration defects surface during the integrated systems test, when the team deliberately kills utility power and watches generators, transfer switches, UPS, and cooling recover together as they should. That's where a sequence built on an assumption the equipment doesn't actually follow gets caught, or an alarm that never routes anywhere gets caught, or a cooling loop that recovers too slowly gets caught.
That test is the last real chance to fix control logic before the vendor's gone. Defects that surface later, in live operation, mean change-authorization paperwork, getting the vendor back on site, and downtime windows that cost far more than thorough IST documentation ever would have. This documentation also underpins the SOPs and MOPs operators will actually follow. Those procedures have to reflect the real facility, not something copied from another site's playbook. This means they can't be finalized until the as-built sequences are locked down.
Security lives in this same handover package. Industry best practice holds that BACnet/SC encryption, network segmentation, and routine firmware updates should be standard, and the control logic package handed to operations should include network architecture and access control documentation alongside the sequences themselves, not as an afterthought.
Where this data originates in design and construction
Point lists start with the mechanical and electrical engineers, who specify what needs monitoring. The problem is that spec rarely travels in structured form from the design documents through BMS programming and into the final handover package. Equipment parameters start in the submittal process, manufacturer data sheets reviewed and approved during construction, then filed as PDFs in a project management system with no automatic link to the BMS configuration.
Alarm configurations tend to get defined late, during commissioning rather than design. Whoever happens to be on site that week decides them, not the operations team that has to live with them for the next ten years. Control logic starts with the mechanical engineer's sequence of operation specs, but field changes during construction routinely drift away from those specs with no formal change control catching the gap.
A recurring finding across the industry is that integration failures usually trace back to starting the integration work too late in construction. The data requirements exist from the design phase onward, but get treated like a commissioning-stage task, which compresses the schedule and shrinks the window for catching mistakes.
A fragmentation problem produces this: the same equipment parameter often gets typed in manually four separate times. The same equipment parameter often gets typed in manually multiple times across the engineer's spec, the submittal log, the BMS programming tool, and the operations asset database. Each transcription is another chance for a typo or a stale value, with nothing automatically checking that they still agree with each other. Connected workflow approaches address this by keeping layouts, critical-systems engineering, equipment parameters, and documentation inside one structured environment, so a change cascades automatically instead of requiring someone to remember to update it across every separate system, including the BMS.
What arrives incomplete at turnover and what it costs
Broadstaffglobal.com's controls staffing research finds that the usual suspects at an incomplete turnover are consistent: chunks of the point list never validated, BMS alarm routing left unfinished, EPMS meter mapping still needing review, and the controls vendor gone after integrated testing wraps, leaving nobody permanently responsible for the controls.
None of that counts as a rare edge case. It's closer to the typical state of a BMS handover on a compressed schedule, because point-to-point validation, alarm routing review, and meter mapping checks all take real time, and that work gets cut when the commissioning calendar shrinks. Proconexdirect.com states that a problem caught during construction costs thousands of dollars to fix. The same problem caught after go-live costs millions, in delays, rework, and downtime. That asymmetry alone is the argument for finishing the job before turnover, not after.
What incomplete data actually produces:
- Unvalidated points push operators back to manual rounds, because they can't trust the readings, which defeats the entire premise of having a BMS and reopens the human-error exposure automation was supposed to close
- Incomplete alarm routing means critical conditions fire alarms that never reach the right team, or reach the wrong team at the wrong priority, quietly, with no one aware anything failed
- Missing EPMS meter mapping means capacity planning runs on bad load data, and an overloaded circuit doesn't get flagged until it trips
- Sequences that were never reconciled against the as-built system leave SOPs written for a facility that doesn't quite exist, so a technician following the procedure to the letter doesn't get the result the procedure promised
None of this appears on a punch list. It appears months later, in an outage report, tracing back to a data gap that was invisible on the day everyone signed off on turnover.
Sources
- BMS Data Center Integration Checklist | SCADA & EPMS
- Data Center Build-to-Operations Handoff: Staffing Mistakes That Create Uptime Risk
- Data Center Controls Staffing: Hiring for BMS and EPMS Reliability
- BMS Guide for Data Center & Facility Leaders
- BMS, SCADA and EPMS: How Data Center Control Systems Work Together - Building Automation & Energy Solutions BMS, SCADA & EPMS: Data Center Control Systems | HBT
- BMS Integration for Data Centers: Cooling, Power, Uptime
- nfmconsulting.com
- nlyte.com